sh. Shuai Hao
Researcher & algorithm engineer

Shuai Hao.

Learning agents.
From research to real systems.

PhD candidate at Beihang University. I work on multimodal reinforcement learning, value models for coding agents, and the systems that bring them into production.

郝帅 / Sergio TermannBeijing, China · Beihang University
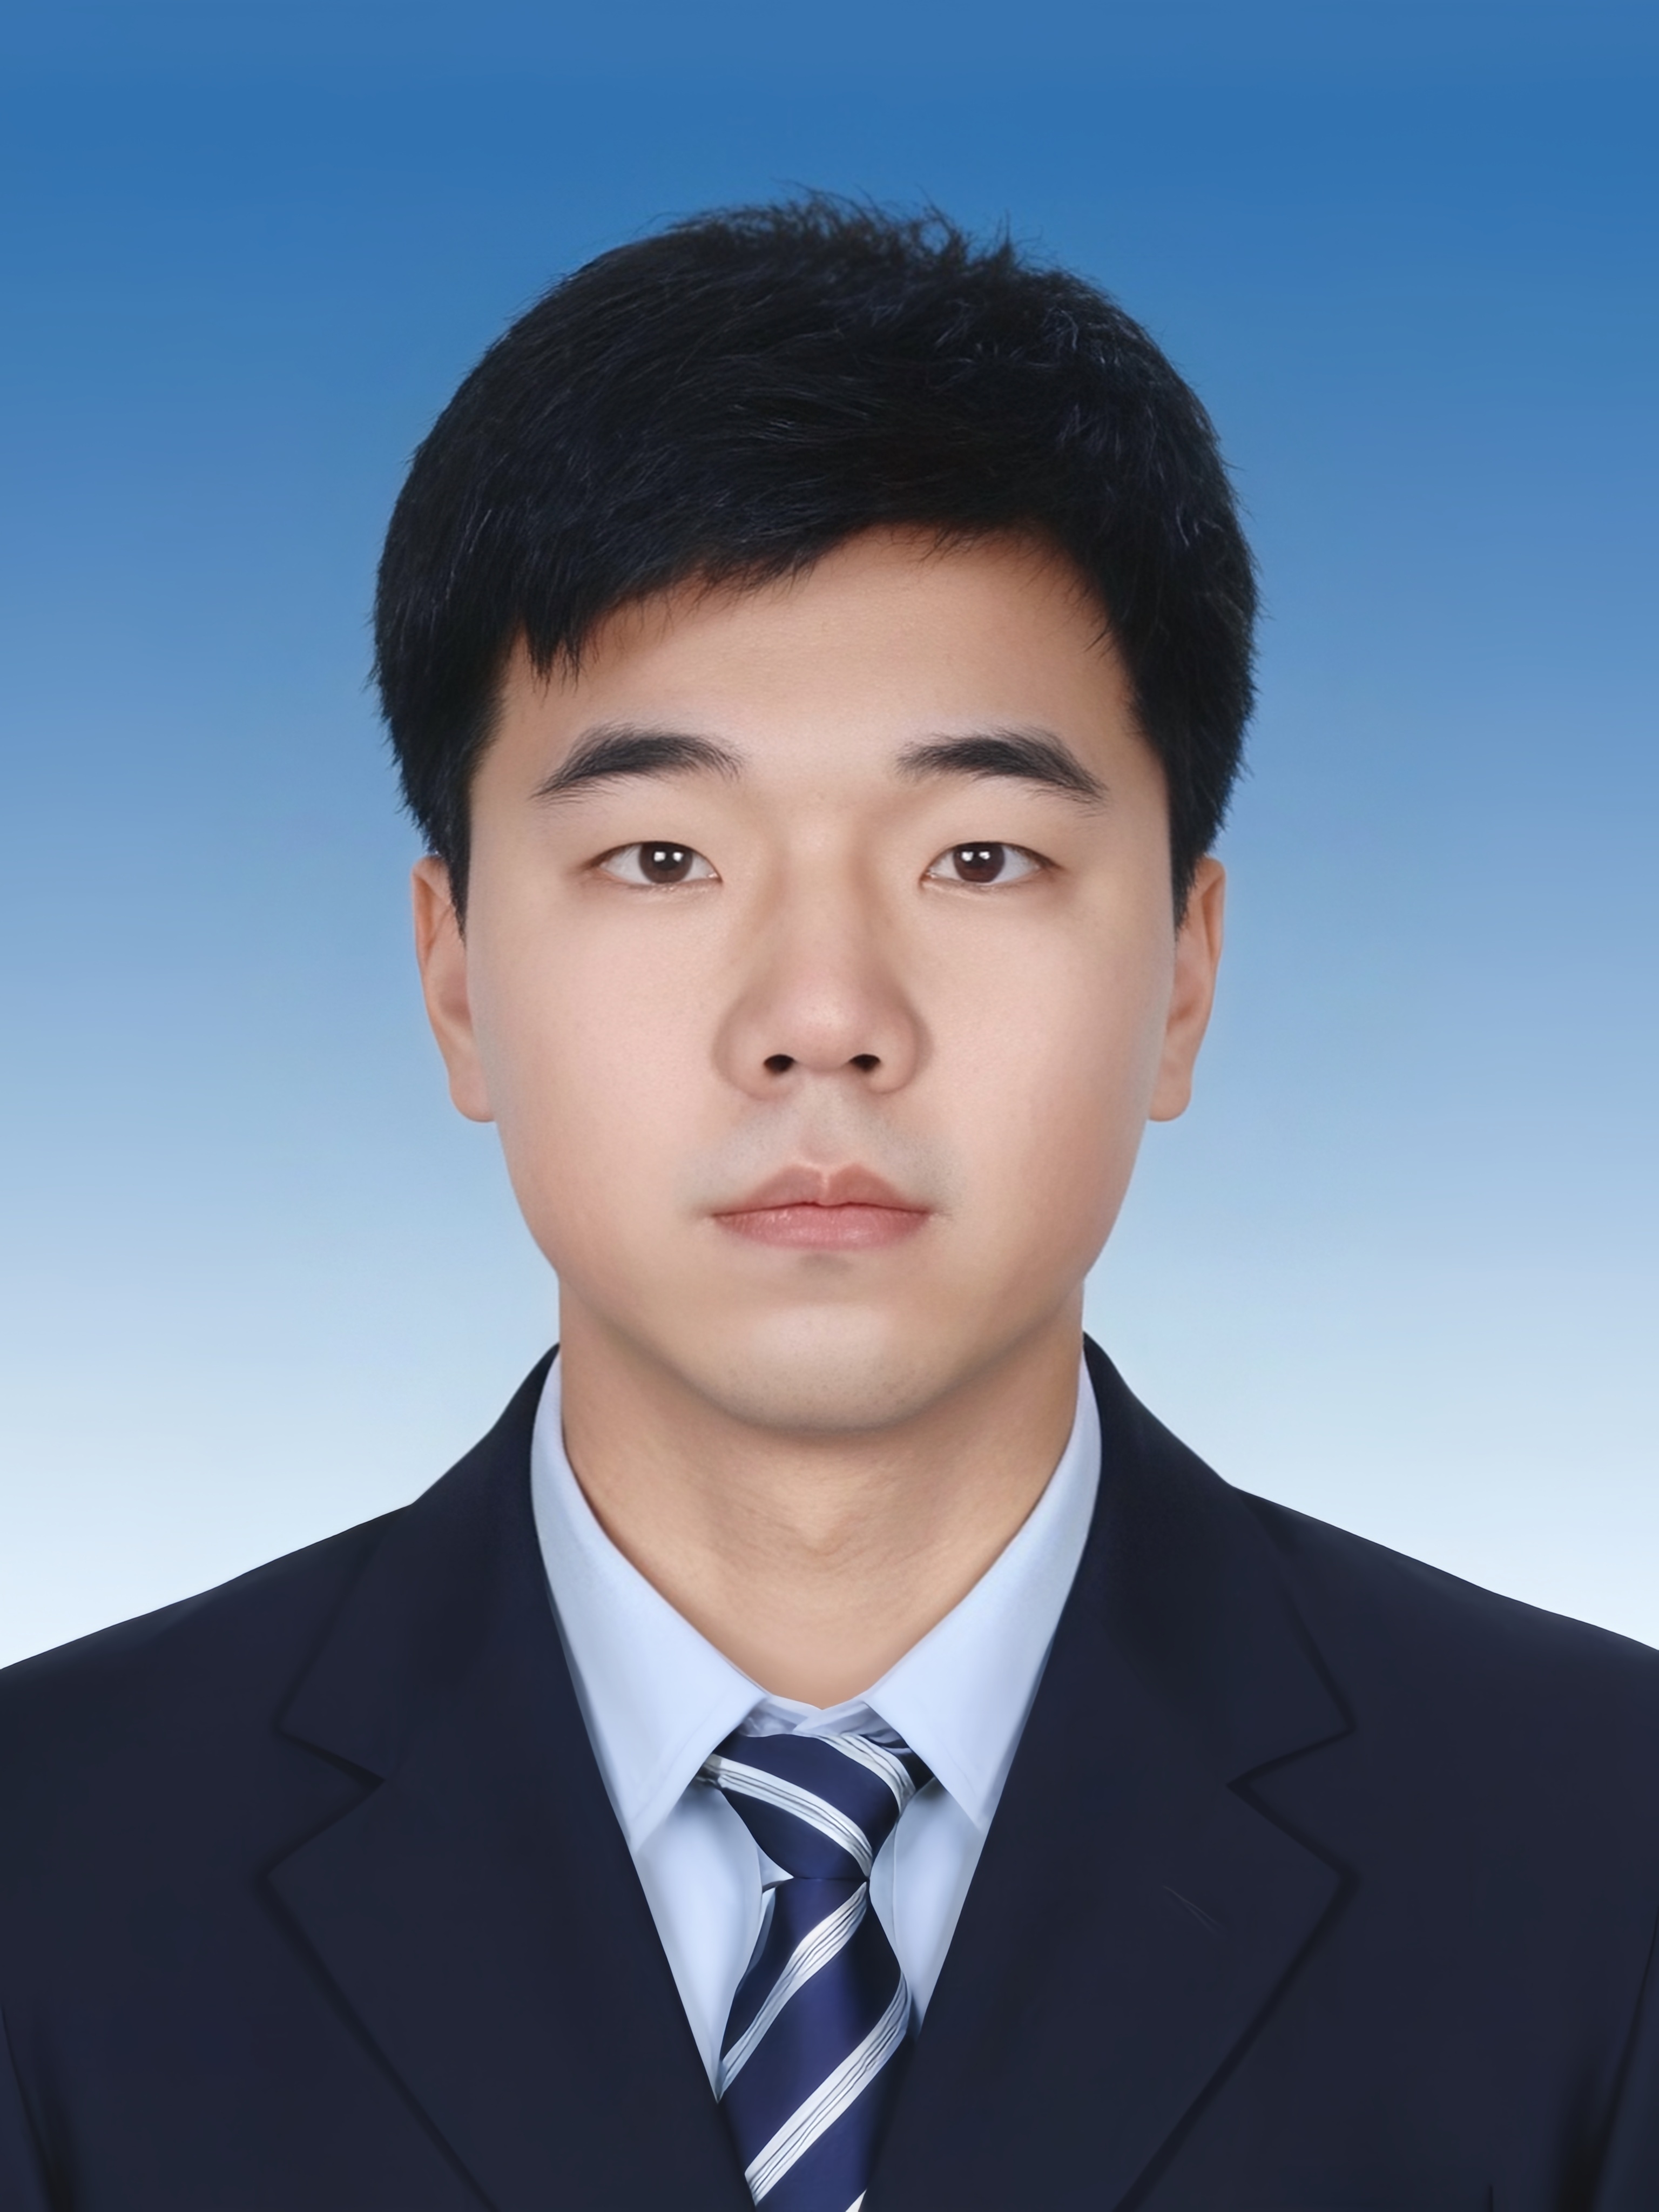
Portrait of Shuai Hao
Research ↔ EngineeringLLM agents · Post-training · RL
Shuai Hao / 郝帅Beijing · CN

A little context.

01 — About

Research into working systems

I connect algorithm design with data construction, reproducible evaluation, and deployment. My research asks how rewards can capture quality, how agents can make reliable decisions over long tasks, and how inference can use a limited compute budget effectively.

Current focus

Agentic RL with RLVR / GRPO, outcome-supervised prefix value models, and set-level reinforcement learning for vision-language models. I am seeking an LLM agent post-training algorithm internship in Beijing, available five days per week for six months.

+12.4%
Improvement in production agent ticket closure
0.926
Best-of-N selection score in coding-agent experiments
+61%
Semantic Volume Score for Geo-RL vs. LLaVA-1.5 7B MLE

Selected work.

02 — Selected work
ICML 2026 2025 - 2026
First student author

Geo-RL for long-form image captioning

Contributed to problem formulation, geometric diversity reward design, credit assignment, implementation, evaluation, and ablations. Geo-RL uses a CLIP-weighted RBF-DPP log-determinant reward, pairwise repulsion, and PPO to balance semantic coverage with visual fidelity. Leave-one-out marginal advantages are computed from one Cholesky factorization. On DeCapBench, compared with LLaVA-1.5 7B MLE, Distinct-2 increased from 0.66 to 0.84 and SVS from 2.20 to 3.55, CLIPScore rose from 0.74 to 0.81, and CHAIRi decreased from 8.3% to 7.1%.

Set-level RL / PPO Geometric Diversity Evaluation Protocol
Prefix Value Model 2026 - Present
First Author · TNNLS Under Review

Prefix value models for long-horizon coding agents

Independently developed the algorithm, data pipeline, experiments, and manuscript. Learned success probabilities from terminal outcomes to support Best-of-N selection and early abandonment. In information-budget-matched experiments, selection reached 0.926 ± 0.049 against a verifier oracle of 0.931 with no extra test execution. Early abandonment saved approximately 15% of end-to-end inference compute with near-zero accuracy loss. LoRA rejection-sampling fine-tuning improved single-pass repair success from 0.375 to 0.800. Built reproducible vLLM trajectory collection and evaluation across Qwen2.5-Coder 7B to 72B.

0.926 vs 0.931 oracle Inference compute savings ~15% 72B · vLLM Outcome-supervised
Beijing Fengqi Shiyu Technology Co., Ltd. Sep 2024 - Oct 2026
Former Partner / AI Team Lead / Project Owner

Production agents for intelligent operations

Led architecture, data, training, and delivery for a Planner-Executor agent with hybrid RAG, function calling, and automatic failure-case feedback. Trained Qwen3-8B with LoRA and TRL GRPOTrainer, using field-level rewards and difficulty filtering to refine 9,215 samples into 2,310 training examples. Slot extraction improved from 0.914 to 0.961. Deployed with vLLM on GPU clusters and reduced iteration time from 1-2 days to under half a day.

Ticket closure +12.4% Tool hallucination 6.8% to 2.9% Qwen3-8B · LoRA RLVR / GRPO
CASIC Intelligent Research Institute Jan 2024 - Mar 2025
Algorithm Intern

Human-guided learning for UAV air-combat simulation

Built a Harfang DogFight simulation and RL training platform, with Gym interfaces, a PyQt5 experiment UI, and PPO / SAC training across 1v1–25v25 scenarios. Collected 2.7 hours of expert demonstrations for GAIL initialization and PPO fine-tuning. Developed vectorized Isaac Lab environments, GPU deployment, and ACMI telemetry with Tacview replay for reproducible simulation evaluation.

Simulation kill rate 2.3x vs. SOTA Engagement duration -30% IEEE SMC Magazine / First author / Accepted
Institute of Automation, Chinese Academy of Sciences Mar 2020 - Mar 2022
Algorithm Intern

RL representation learning and distributed training

Designed QIARL with Q-irrelevance state abstraction and validated it in PyTorch and TensorFlow on Procgen. Built a learner-actor architecture with ZeroMQ, multiprocessing, and shared memory, then migrated it to Ray / RLlib. Established reproducible multi-agent training and evaluation with SMAC, PyMARL, RLlib, and MADDPG / MPE.

Sampling throughput ~10x QIARL Ray / RLlib

Research & publications.

03 — Publications
  • IEEE SMC Magazine · 2026
    Human-Guided Autonomous Learning for UAV Air Combat Decision Optimization
    First author · Accepted
  • TNNLS · Under Review
    Outcome-Supervised Prefix Value Models for Best-of-N Selection and Early Abandonment in Long-Horizon Coding Agents
    First author · Under review
  • ICML · 2026
    Escaping the Likelihood Trap: Geometric Diversity Optimization for Long-Form Image Captioning
    First student author
  • ICICIP · 2021
    Learning Representation with Q-irrelevance Abstraction for Reinforcement Learning
    First author

Tools of the trade.

04 — Expertise
01

LLM Post-training

  • GRPO / PPO
  • SFT / LoRA
  • Reward Engineering
  • PRM / PVM
  • Best-of-N
02

Agent Systems

  • Planner–Executor
  • Hybrid RAG
  • Function Calling
  • Agent Trajectory Construction
  • SWE-bench Evaluation
03

Reinforcement Learning

  • PPO / SAC / GAIL
  • Multi-agent RL
  • Ray / RLlib
  • PyTorch / TRL
  • LoRA Fine-tuning
04

Inference & Systems

  • vLLM / Tensor Parallelism
  • Distributed Sampling
  • GPU Clusters
  • Isaac Sim / Lab
  • Harfang DogFight

Academic roots.

05 — Education
  • 2022.09 - Present
    Beihang University
    School of Automation Science and Electrical Engineering
    PhD Candidate
  • 2019.09 - 2021.12
    Beihang University
    School of Software
    Master's Degree
    Outstanding Graduate of Beijing
    Outstanding Graduate Student of Beihang University
  • 2014.09 - 2018.06
    Beijing Institute of Technology
    School of Optics and Photonics
    Bachelor's Degree
    Outstanding Undergraduate Thesis

Along the way.

06 — Beyond the work
  • NeurIPS / AIcrowd
    Procgen Reinforcement Learning Challenge
    7th of 82 teams; first among universities. Led algorithm development, Ray / RLlib trainer changes, data augmentation, and hyperparameter search across 12 environments.
  • 2023
    Air Force Unmanned Systems Challenge
    Excellence Award in the 2v2 simulation track; first among non-military universities.

Beyond research: Beihang table tennis team member (Beijing rating 1650). SolidWorks, Blender, CAD, 3D printing, and indoor/outdoor quadrotor swarm control. German A1.

Open to opportunities

Let’s build learning agents.

Seeking an LLM agent post-training internship in Beijing.
Available five days a week, for six months.

Get in touch